
RAG Architecture and Anti-Hallucination
Master the RAG execution loop, context assembly, truncation strategies, evaluation metrics, and anti-hallucination engineering controls.
Retrieval-Augmented Generation (RAG) is a critical architectural pattern combining static knowledge assets with large language models. FastGPT combines retrieval, reference prompts, and citations to reduce unsupported answers. Validate factual accuracy with a representative test set.
The Complete RAG Execution Loop
A configured RAG pipeline can contain the following phases. Query rewriting, hybrid search, and reranking depend on application settings:


Core Evaluation Metric Framework
Evaluating knowledge base RAG performance centers around four key dimensions:
| Metric | Definition and Focus | Optimization Levers |
|---|---|---|
| Recall | Whether the chunk containing the ground truth was successfully retrieved | Adjust chunk boundaries, enable hybrid search, tune embedding models |
| Precision | Proportion of retrieved chunks that provide direct factual value | Integrate Rerank models for second-pass scoring; increase Lowest correlation thresholds |
| Context Redundancy | Density of irrelevant information in the model context | Refine chunk size limits, lower citation token budgets, eliminate duplicate data chunks |
| Factual Faithfulness | Degree of alignment between model statements and cited reference material | Strengthen prompt constraints, select models with strong instruction-following capabilities |
Context Assembly and Token Budgeting
Large language models feature maximum context window boundaries, and model attention degrades across lengthy prompts. FastGPT enforces structured context assembly rules:
- Token Allocation: The system partitions context into four allocations: global system prompt, multi-turn history, retrieved knowledge chunks, and completion token headroom.
- Relevance Ordering: Candidate order follows the active retrieval and reranking configuration. Inspect the returned references to confirm that relevant evidence survives selection.
- Safe Boundary Truncation: Retrieval keeps whole chunks and can cross the token-budget boundary with its final chunk. The AI Chat stage applies its own reference limits; inspect the final assembled context.
Three Pillars of Anti-Hallucination Engineering
Use the following controls and verify their behavior in the published application:
1. Grounded System Instructions
Define explicit operational boundaries within the prompt:
You are a corporate policy assistant.
Answer user questions strictly using the retrieved reference material below.
When the references do not record the requested information, respond that the documentation contains no record, identify the missing details, and direct the user to the appropriate department.
Do not infer unrecorded figures, deadlines, or promises from external knowledge.
2. Hard Lowest Correlation Threshold Filtering
Calibrate Lowest correlation thresholds using labeled queries and verify the active score-filter mode. Configure and test an empty-result branch or insufficient-evidence prompt in the application.
3. End-to-End Citation Transparency
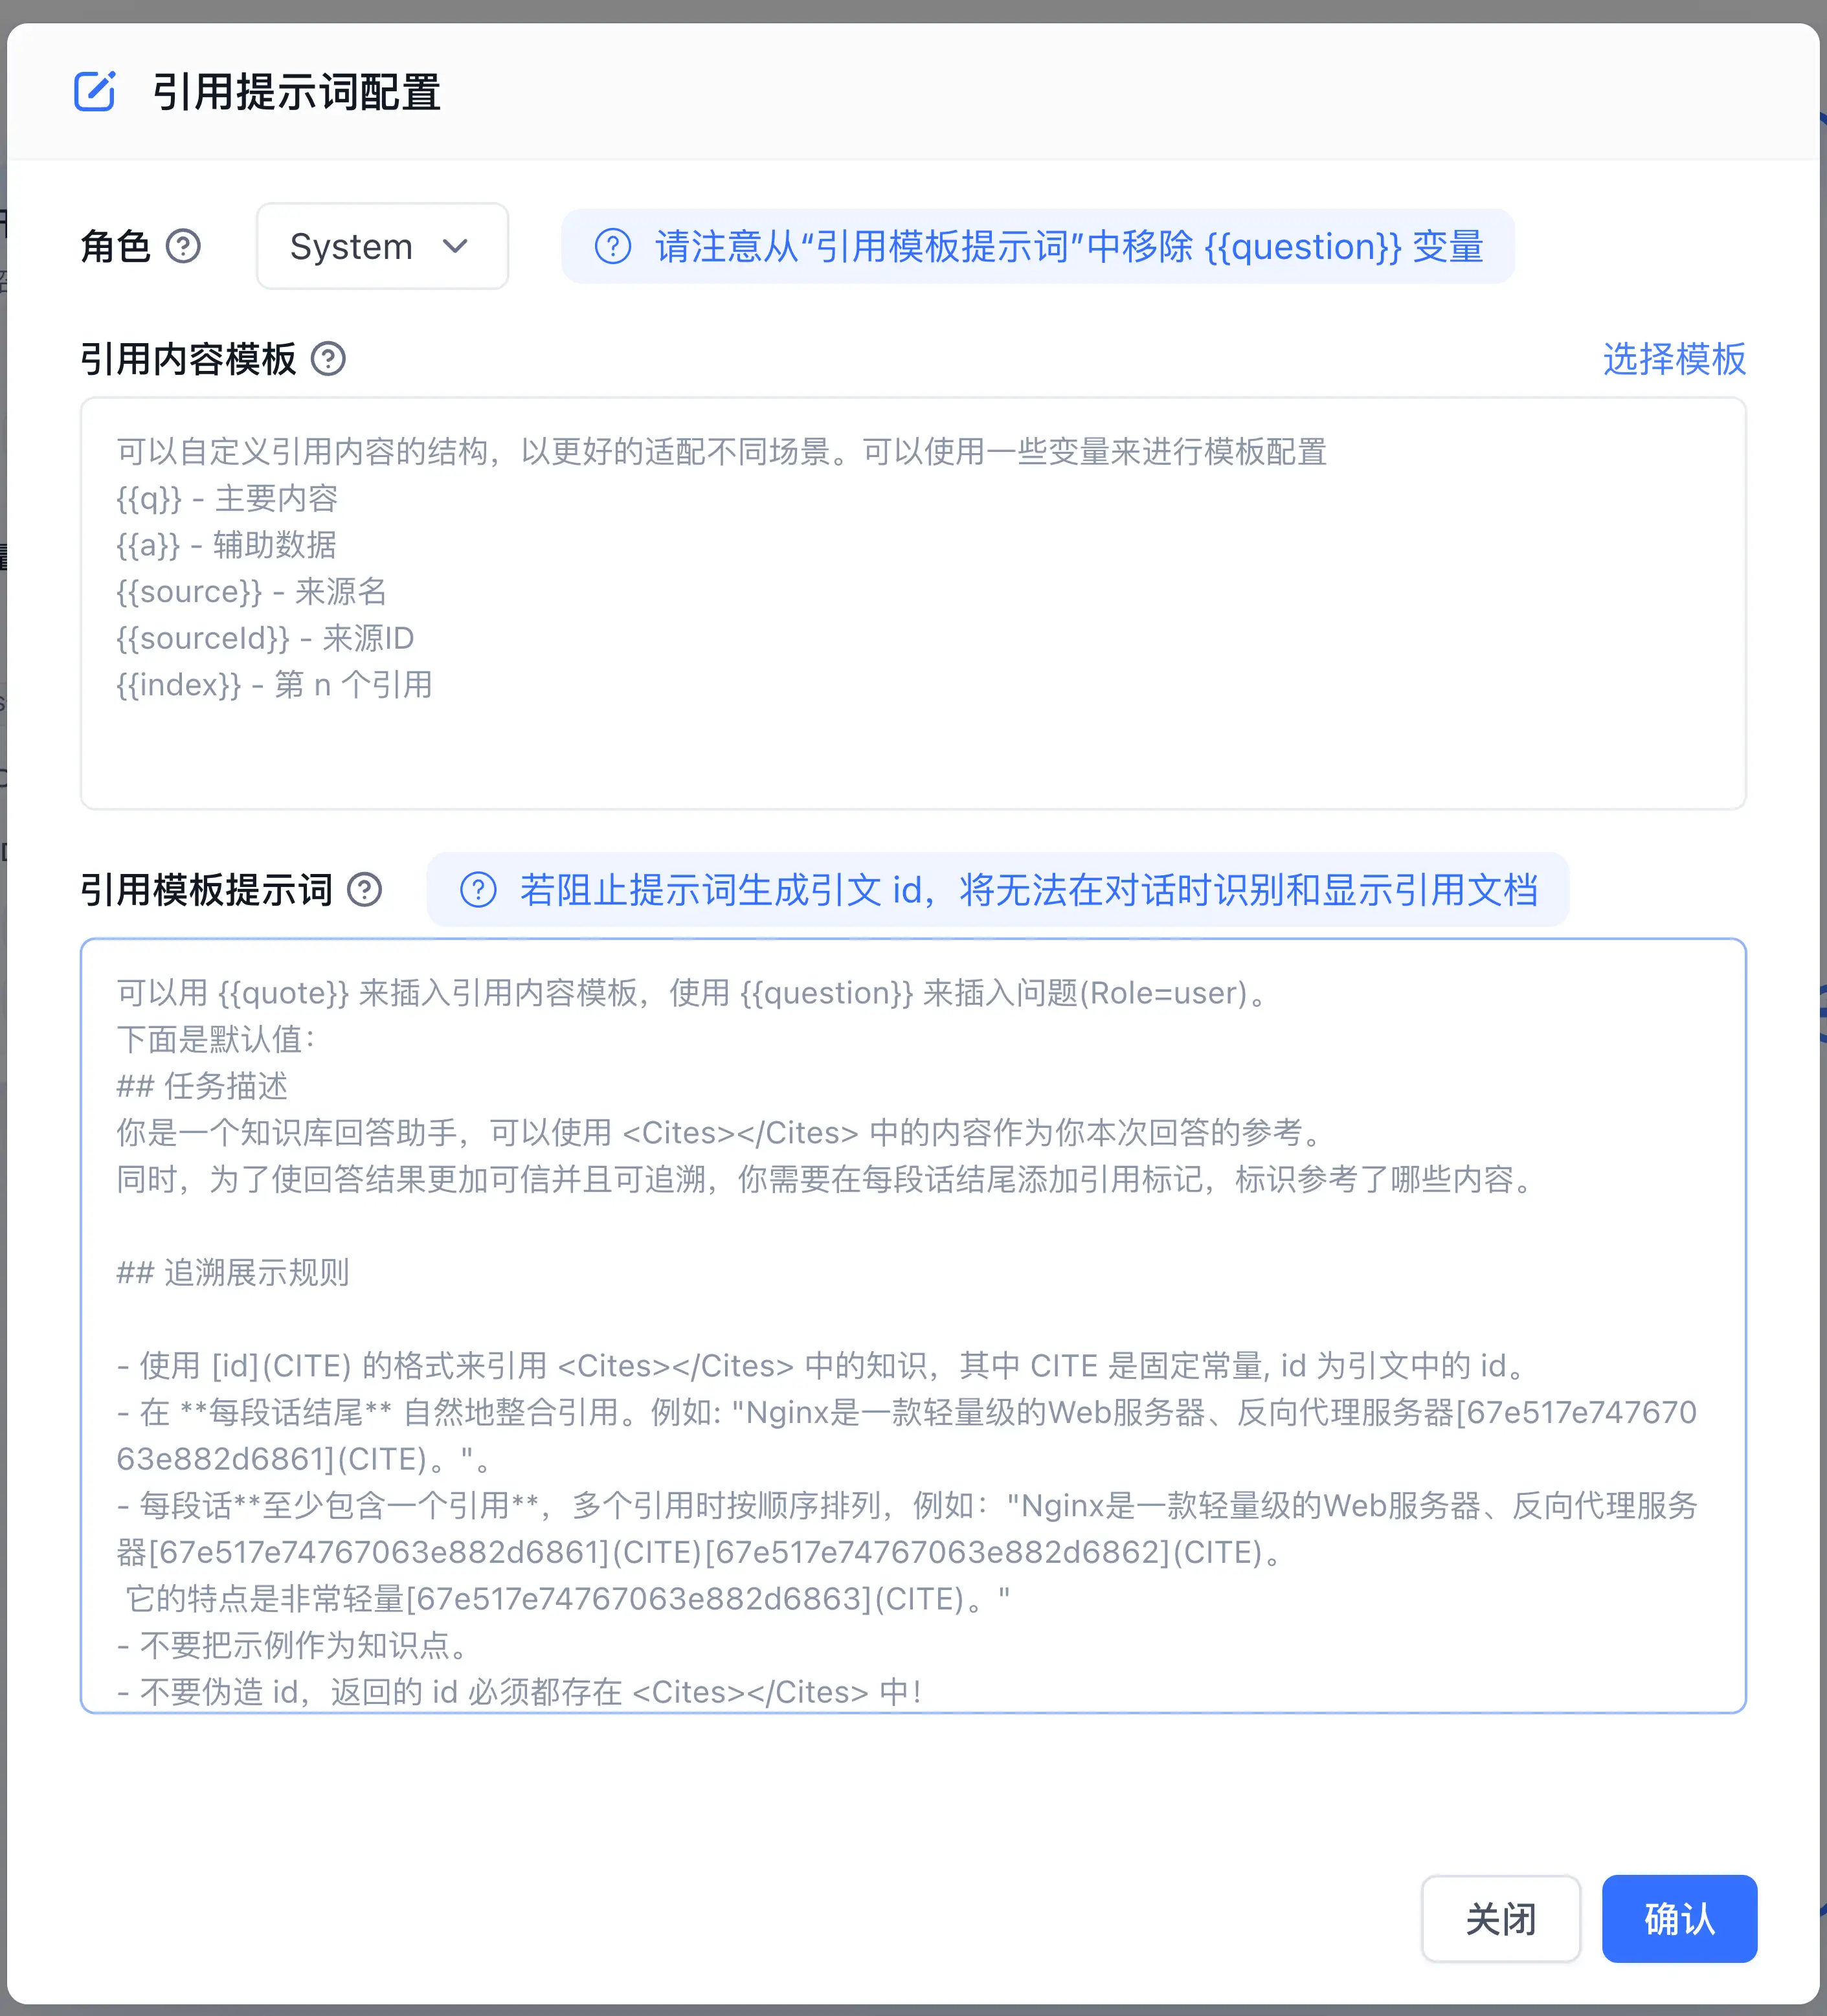
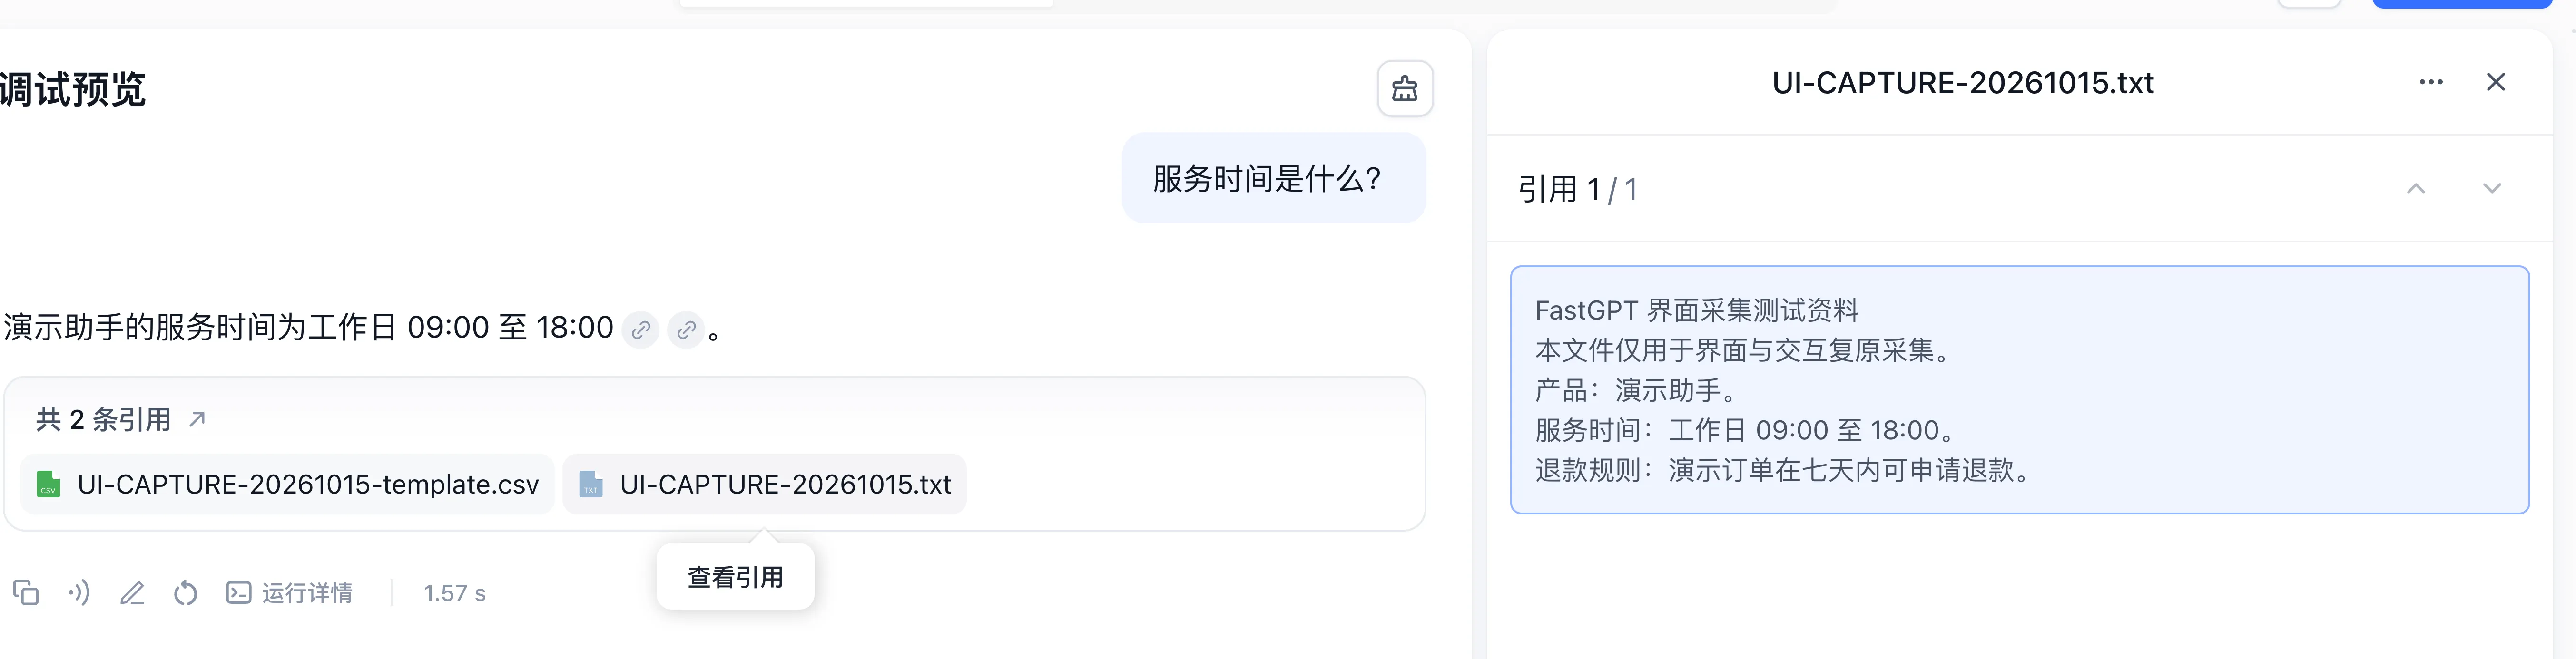
During response generation, the engine tracks and outputs the source file name, chunk text, and collection ID for each used candidate. Front-end chat widgets render clickable citation pills, enabling business users to verify statements against source text.
Next Steps
- Test retrieval scores: Follow Search Testing and Retrieval Parameters.
- Connect to conversational models: Follow Connecting Knowledge Bases to Applications.
- Granular search filtering: Review Collection Tag System.
Last updated